
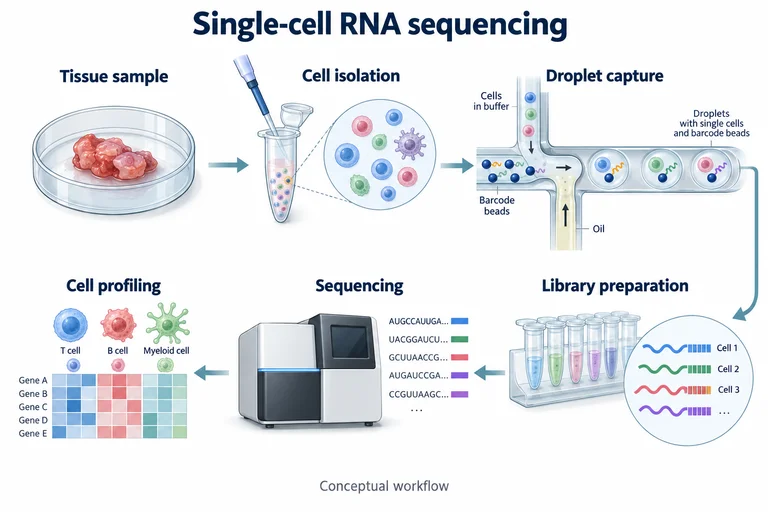
Single-cell RNA sequencing
Connect six illustrated sample and instrument stages.
Use this promptComputing & research methods Question, approach, finding
Bring two encoding branches into a shared fusion module.
Replace the example subjects, steps and findings with your research before generating.
Use the prompt to start with the example description, or use the image as a composition reference while keeping your own text.
Browsing and copying are free. Generation uses the credits shown in the maker.
Connect six illustrated sample and instrument stages.
Use this prompt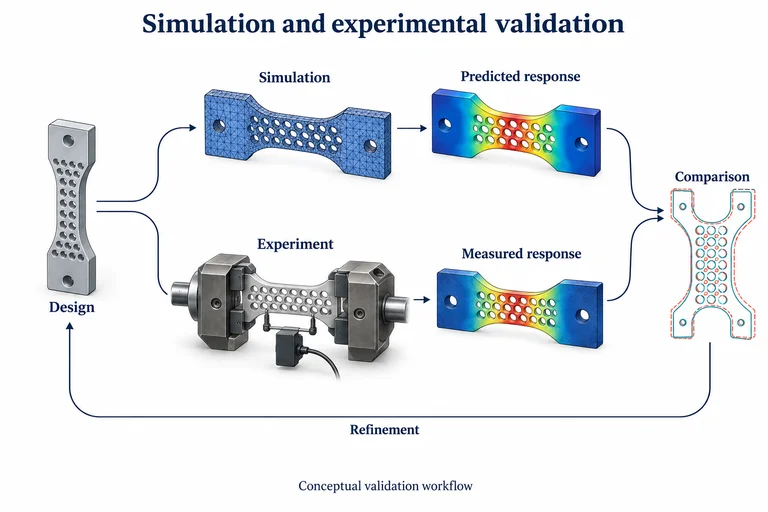
Branch one design into simulation and experiment, then compare.
Use this prompt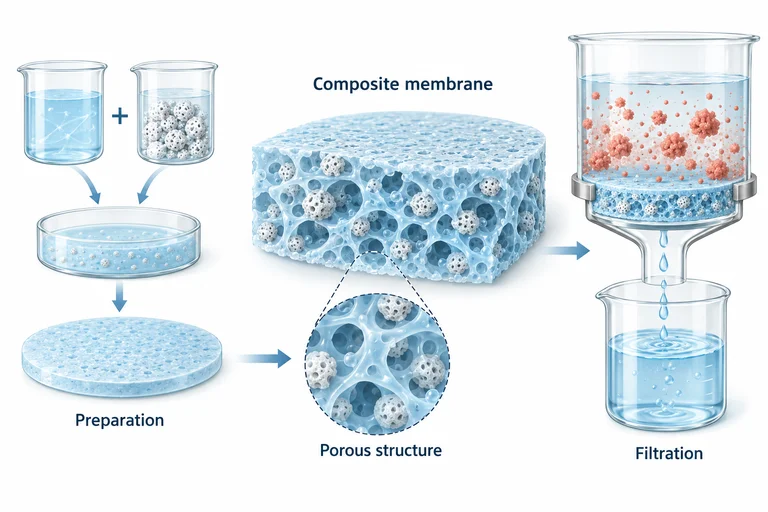
Link preparation, pore structure and filtration in one reading sequence.
Use this prompt